For years, storage teams have had plenty of data and not quite enough context.
Most ONTAP estates are watched two ways today. Active IQ Unified Manager gives the overall view, and it has done that job faithfully for a long time. But it is legacy now. It has no agentic capabilities, and it does not cover the newer platforms teams are buying—an ASA R2 controller simply does not appear there. Everything else happens in System Manager, which is a genuinely good interface for one cluster at a time. That is exactly the limitation: one cluster at a time.
So the estate-level question—which system needs me first?—either goes to a tool that cannot see all of it, or gets answered by opening System Manager repeatedly and holding the comparison in your head. And once you find the problem, seeing it and fixing it are still two different places.
That is the gap the NetApp Console local deployment closes.
Console local brings fleet management, observability and day-to-day operations into an on-premises control plane. That last point matters. In a regulated environment, a sovereign data center or a dark site, "send the telemetry to a SaaS service" may simply not be an option. Console local keeps the operational experience local while still giving teams a fleet-wide view.
Start with the fleet, not the cluster
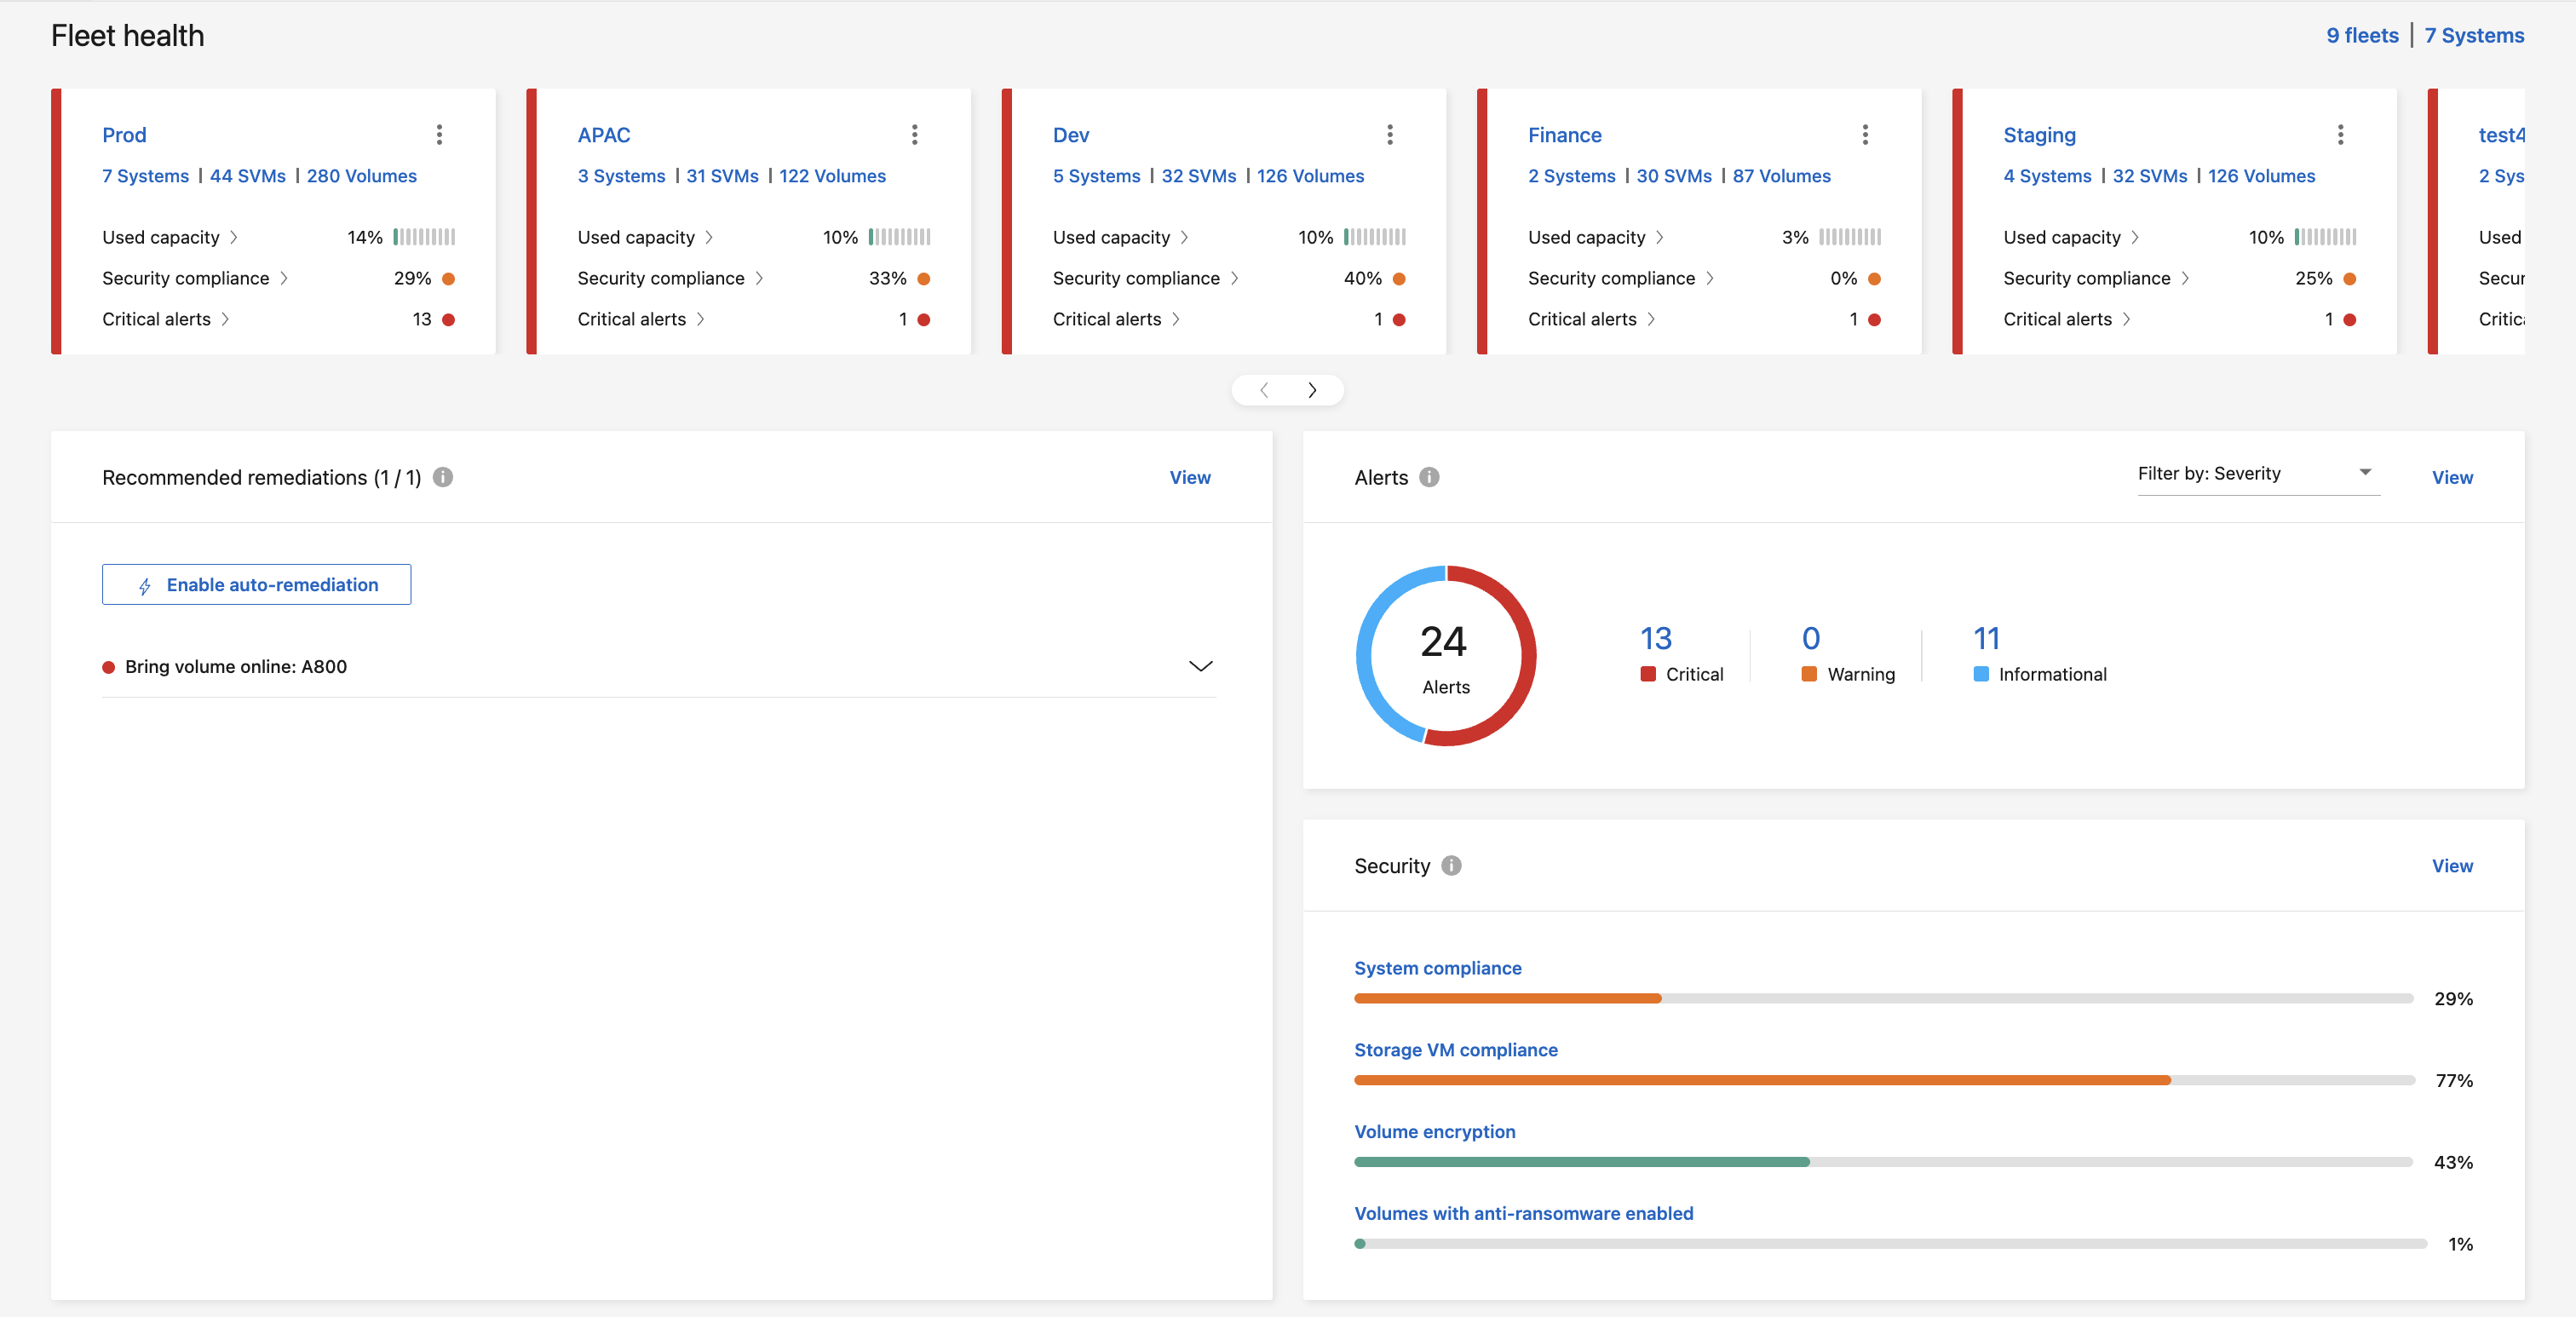
Console local starts at the level the question is usually asked. It gives an operations team a common view across the ONTAP fleet—systems, capacity, performance and health—including the newer platforms that legacy monitoring never learned to see. The estate can be grouped the way the business is actually organised, so a fleet health view can show Dev, Finance, APAC and Prod side by side, each with its systems, storage VMs and volumes, used capacity, security compliance and open critical alerts. From there, an administrator can move from an estate-level signal down to a cluster, workload or volume without starting the investigation over somewhere else.
This sounds like a small change in navigation. In practice, it changes the morning routine. Instead of working through clusters one at a time, an administrator can answer a few basic questions in one place:
- Where is capacity growing faster than expected?
- Which systems are carrying active critical alerts?
- Is a latency problem isolated to one workload or visible across the fleet?
- Which issue should the team work on first?
Underneath, Console local draws on the full depth of NetApp Harvest metrics—so this is not a thinner view of the estate than administrators are used to. It is the same class of data, presented in the environment where the fleet is actually managed.
Dashboards that answer the team's questions
A fixed overview is useful, but an infrastructure lead and a storage administrator rarely need the same view.
Custom dashboards let teams arrange the signals that matter to them: capacity by cluster, latency trends, top workloads by IOPS, protection status and recent alerts, for example. Multiple visualisations make it possible to look at the same estate from different angles without exporting data into a spreadsheet first.
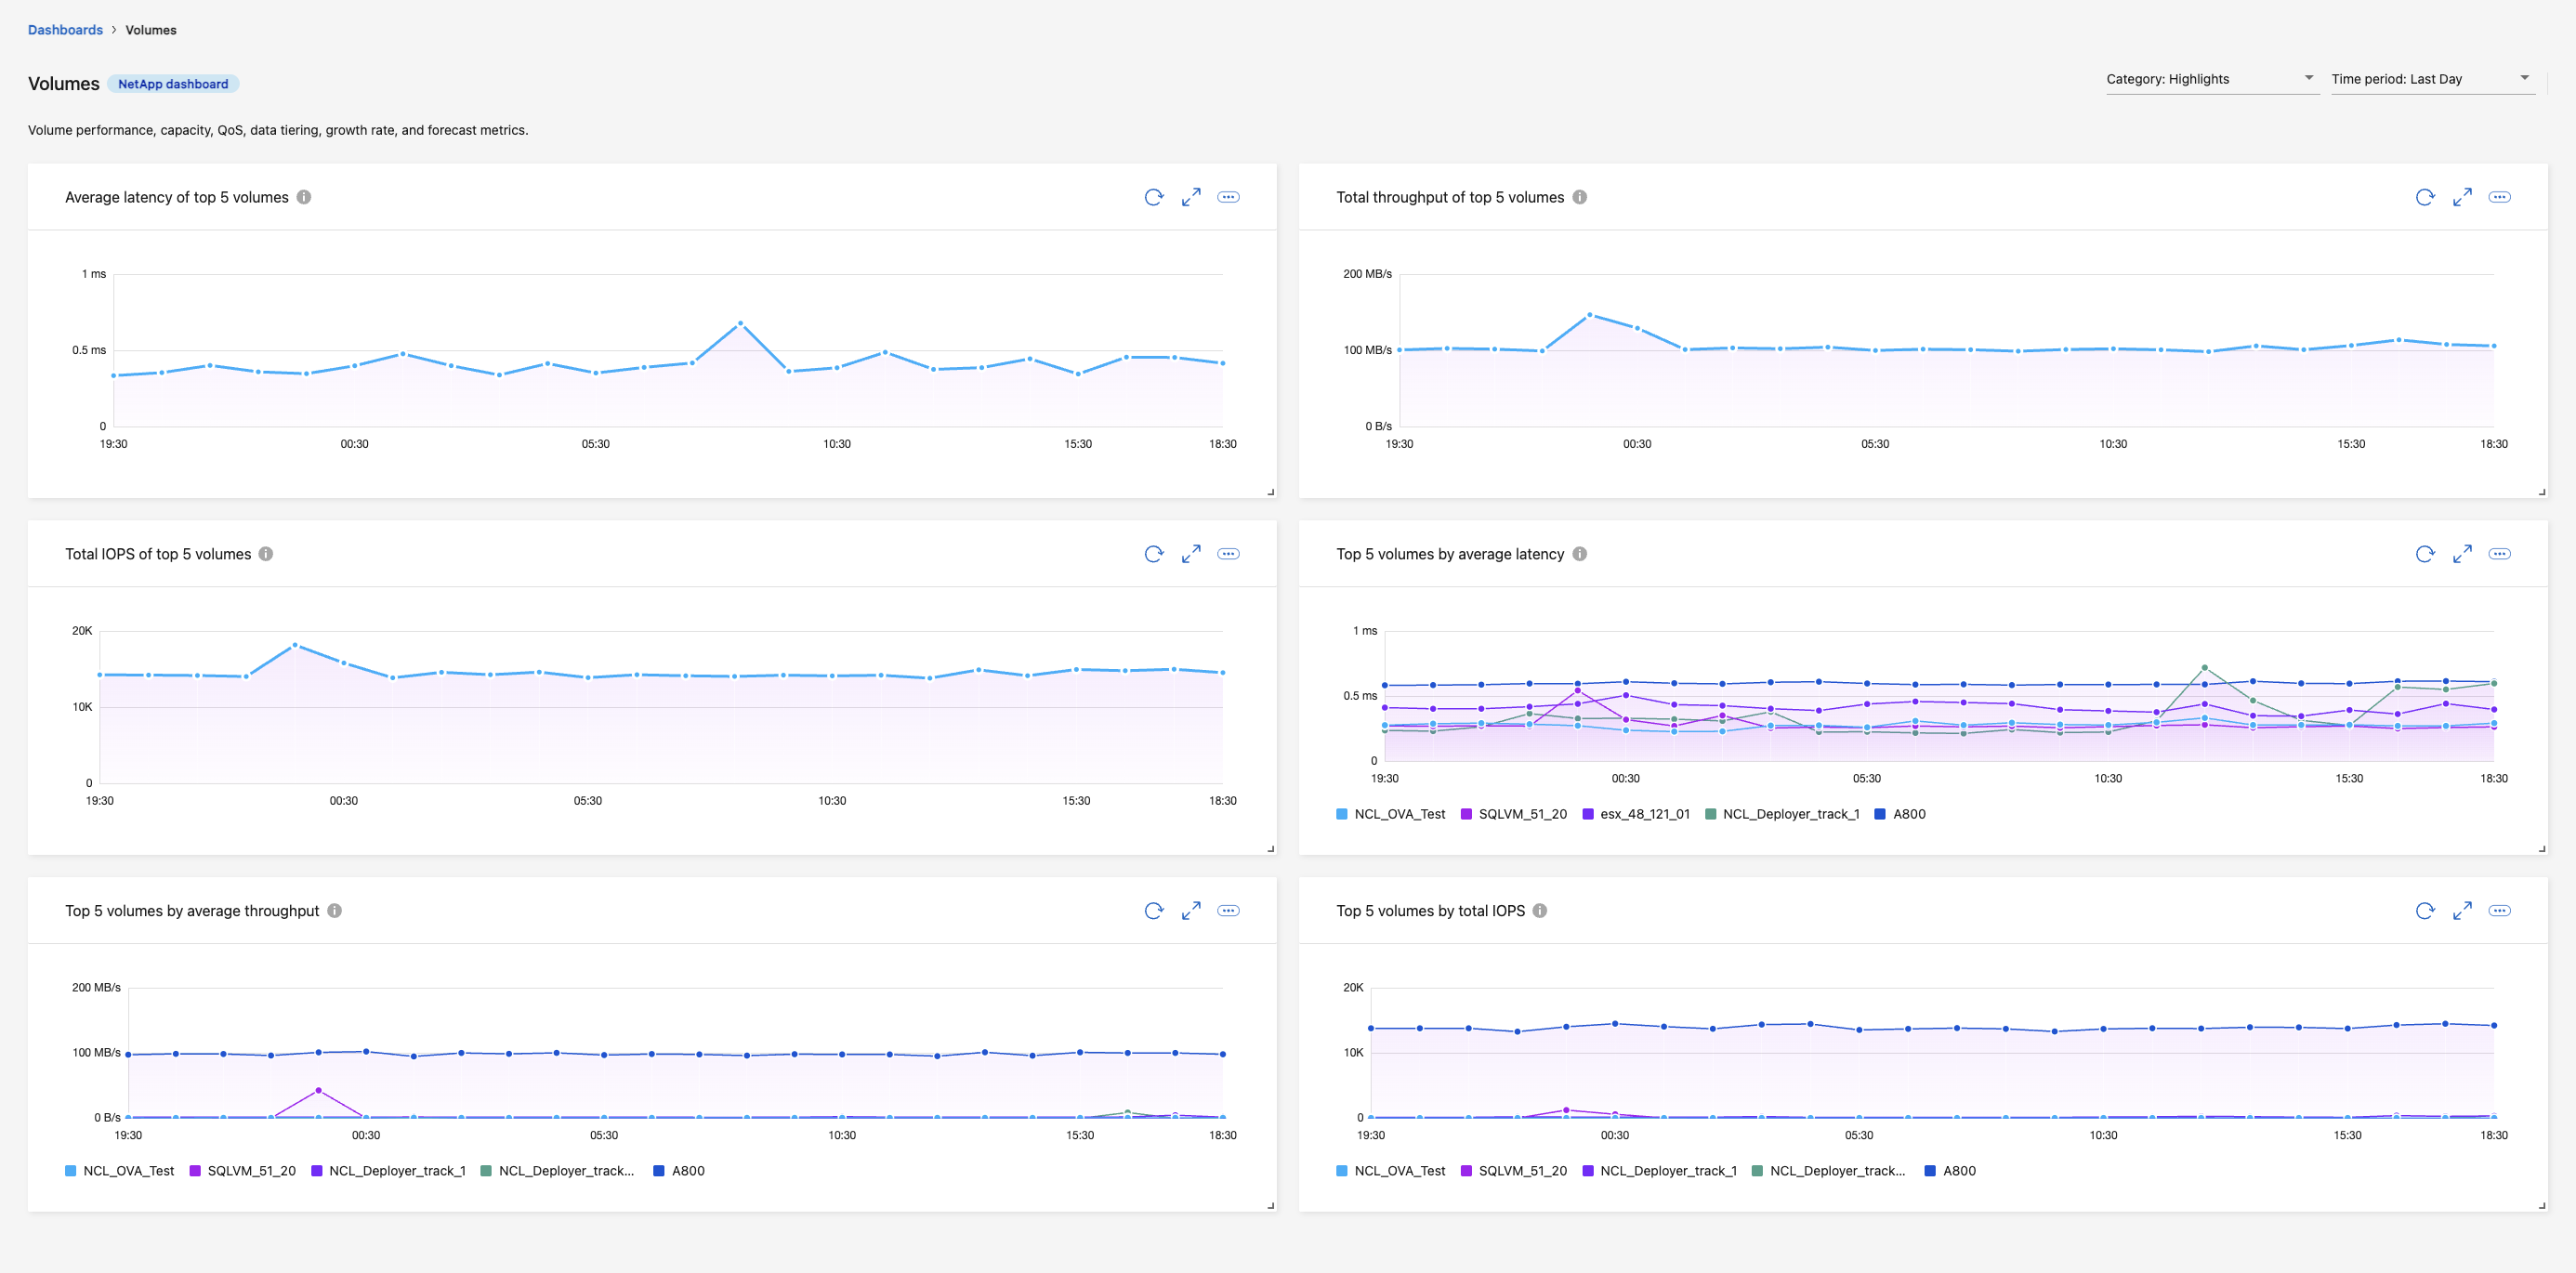
The first three charts—average latency, total throughput and total IOPS—also show the top 5 volumes. They are drawn as a single line, so a per-volume legend is not shown.
The practical value is not the chart itself. It is the ability to notice a relationship. A capacity warning beside a rising workload trend tells a more useful story than either signal in isolation. A protection panel beside recent infrastructure alerts helps an operator understand whether an incident is merely noisy or has started to put recovery objectives at risk.
For a deeper investigation, the Workload Analyzer narrows the view to an individual volume. Its guided flow brings together the event timeline, latency, throughput, resource utilisation, capacity and data protection. That gives an administrator a sensible path through a performance case instead of a blank query box and a wall of metrics.
Alerts with enough context to be useful
Most infrastructure products can produce alerts. The real test is whether an alert helps someone decide what to do next.
Console local provides a fleet-wide alert view with search, filtering and detailed information about the affected resource. Alerts follow a consistent model: three severities—Critical, Warning and Info—and six impact areas covering Availability, Capacity, Performance, Protection, Security and Configuration. That consistency becomes important as more services contribute signals to the same console.
Notifications also stay on premises. Teams can route them through email, webhooks or the Console notification bell, including in environments without internet connectivity. Rules can be tailored so the right group sees the right events rather than receiving every signal produced by the estate.
There is an equally important detail behind the scenes: alerts are expected to be edge-triggered, so a condition raises an alert when it becomes true rather than on every evaluation cycle. Services are also encouraged to resolve alerts automatically when the underlying condition clears. Both choices help keep the alert list closer to an operational queue and further away from a historical dumping ground.
From "something is wrong" to "here is a safe next step"
This is where the NetApp Console local deployment becomes more than a monitoring console.
Where a condition has a supported fix, Console local surfaces it as a recommended remediation rather than leaving the operator to go elsewhere and apply it by hand.
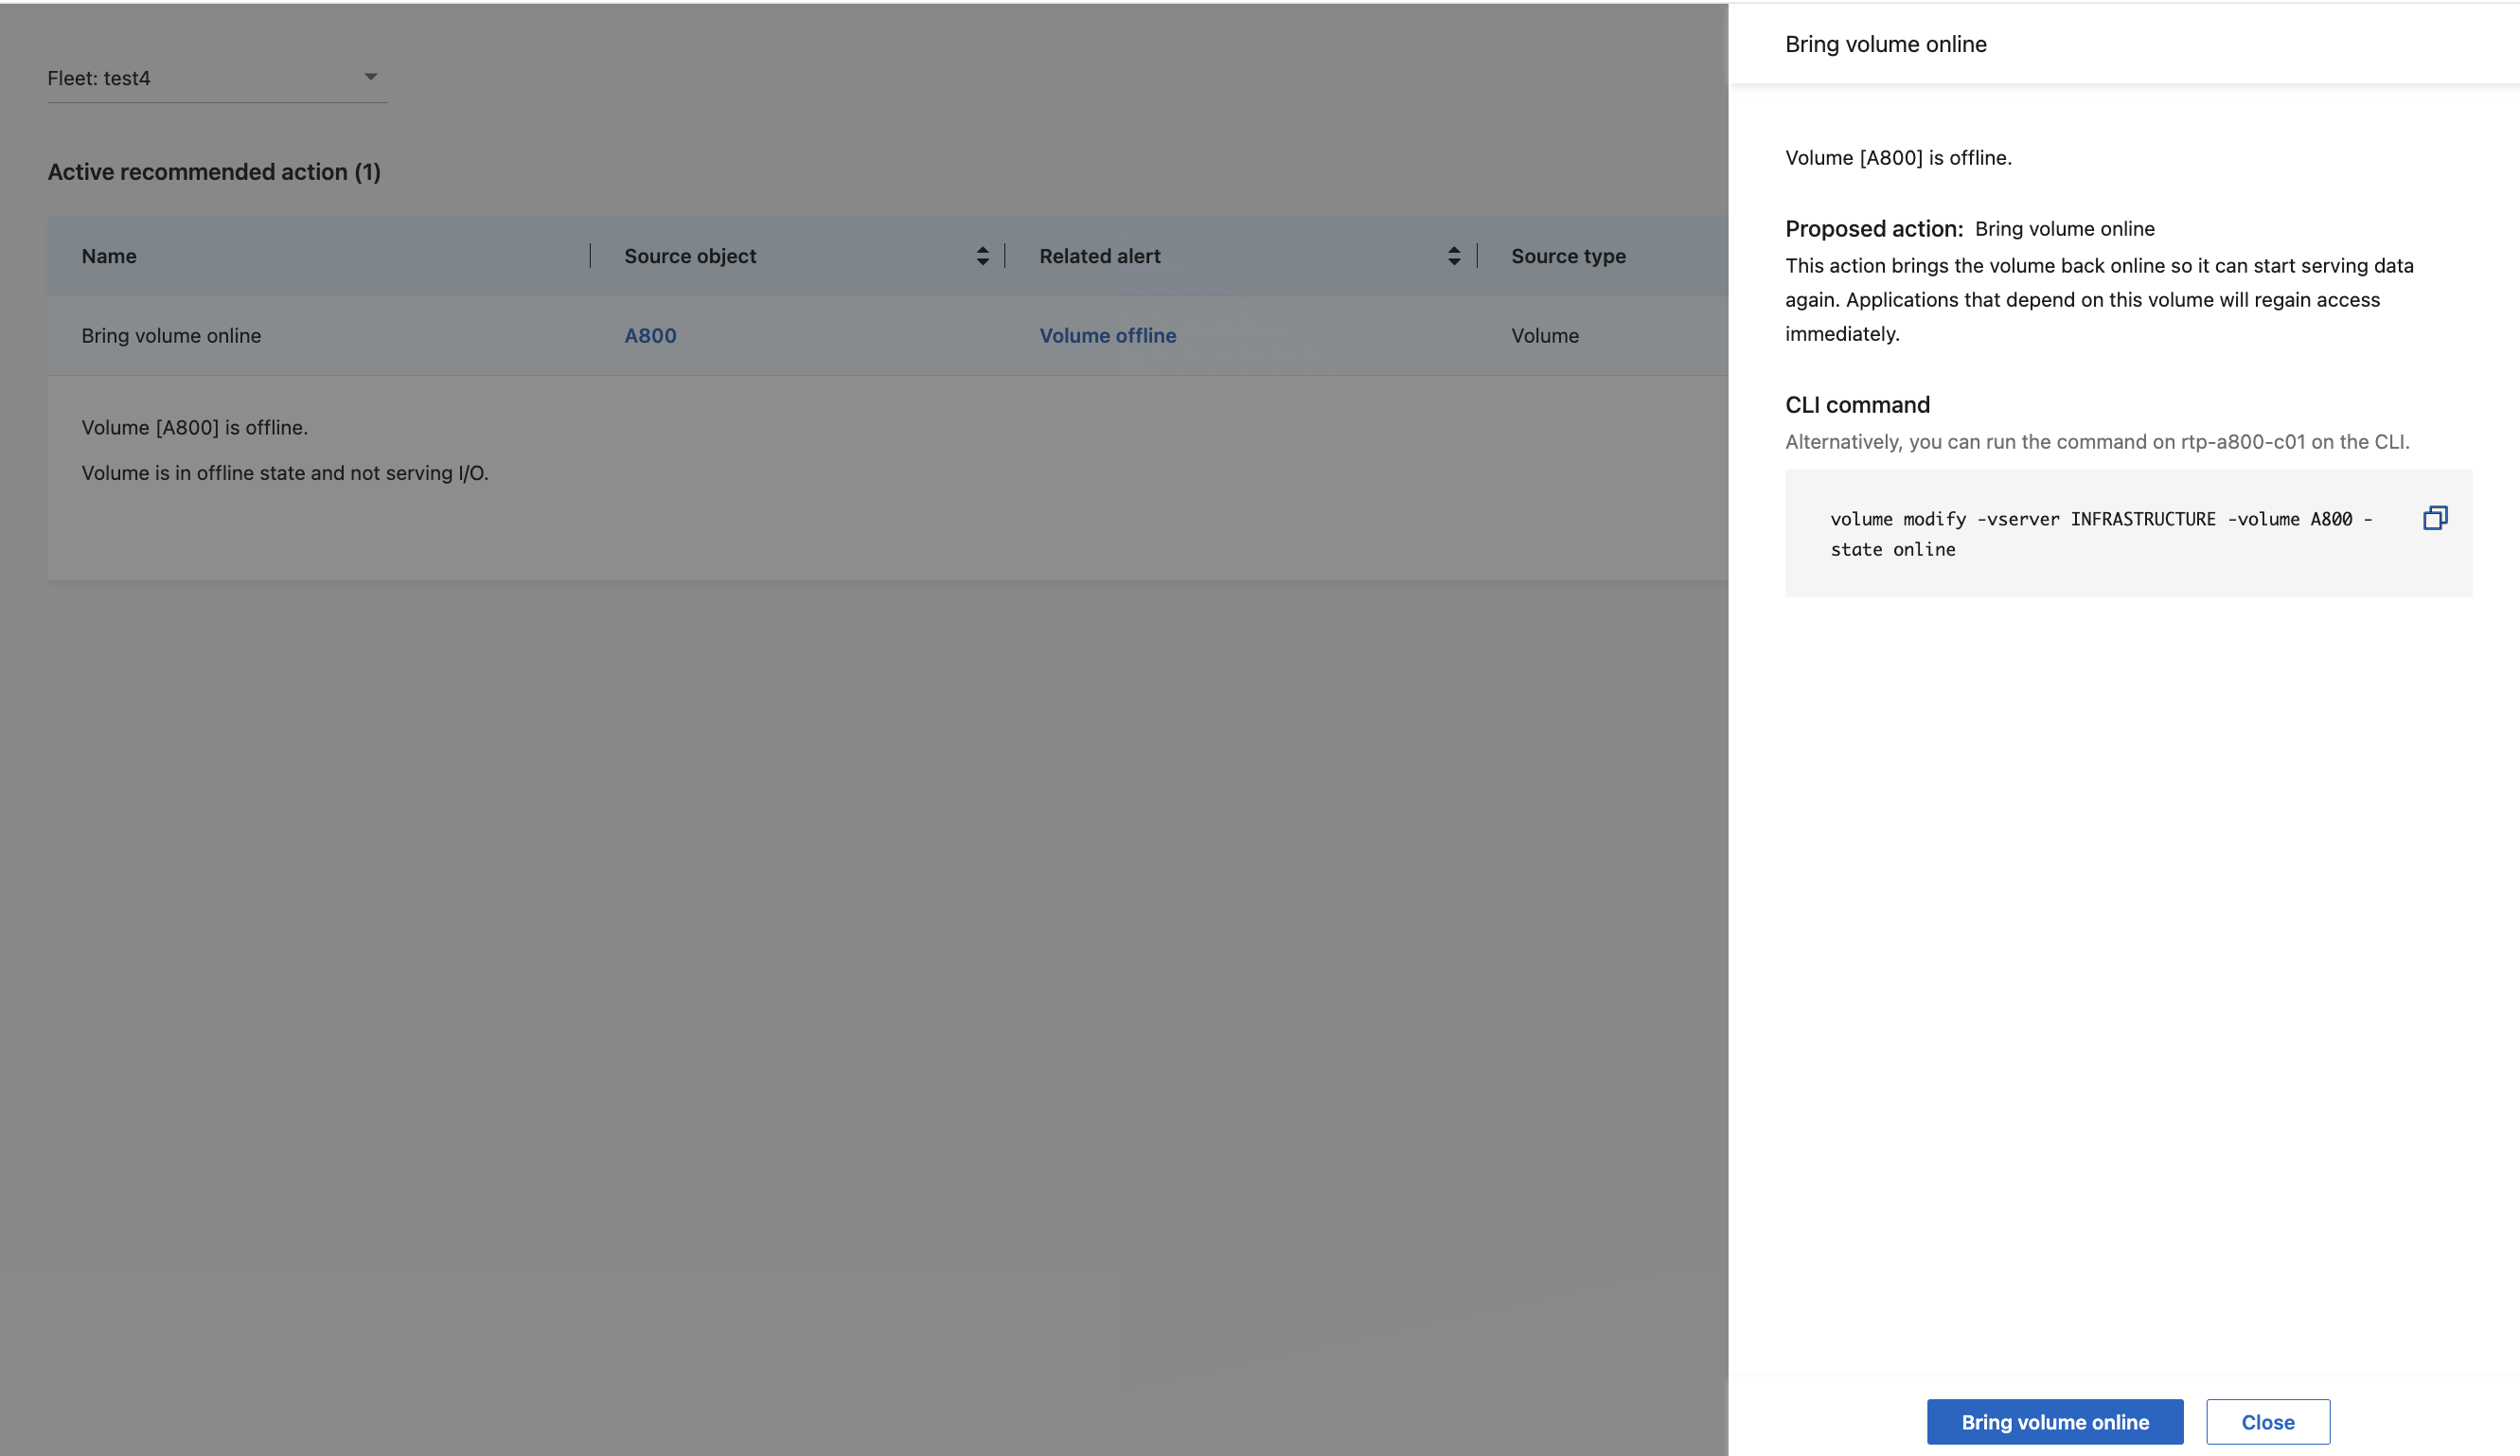
Choosing Fix it opens the action with the context needed to judge it: what Console local proposes to change, the current state of the object, the constraints that affect the result, and whatever input the operator must supply. The equivalent CLI command sits alongside it, for anyone who would rather run the change themselves or fold it into automation.
The panel is built around getting the decision right before it is applied. The initial set is deliberately narrow, covering common volume-management actions, and an auto-remediation setting exists for teams ready to let recommended fixes run on their own.
The loop also removes a hand-off. Nobody has to copy an object name into another console, rebuild the context there, and hope they are changing the right thing.
The bigger shift
All of this runs inside the customer's own environment. The control plane, the metrics, the alert history and the notification path stay on premises, which is what makes the NetApp Console local deployment workable for air-gapped sites, regulated organisations and anyone operating under data-sovereignty rules. Monitoring stops being one more thing that depends on an internet connection.
Running locally no longer means accepting less. An on-premises deployment gives fleet-wide monitoring, role-based access and local notification routing, and it covers the platforms an estate is buying today rather than the ones it bought a decade ago. It connects those metrics to inventory, alerts, workload context and management actions, so the work moves in one line: start with the fleet, narrow to the resource, understand the risk and—where a supported remediation exists—fix it without leaving the console.
The most useful observability platform is not the one with the most charts. It is the one that shortens the distance between a signal and a safe decision. That is the direction the NetApp Console local deployment is taking: from monitoring storage to operating the fleet.
Call to Action
If Console local is new to you, start with the launch announcement: Rethinking On-premises Storage Management at Scale. It covers what the NetApp Console local deployment is, why we built it, and everything it does beyond observability—fleet organization, storage classes and the Console AI assistant.
When you are ready to see it against your own estate:
- Download the NetApp Console local deployment OVA from the NetApp Support site and deploy it into a non-production VMware environment.
- Add a handful of clusters and group them the way your business is actually organised. One site and a named admin is enough to see whether the fleet view earns its place.
- Take one alert your team genuinely cares about and follow it all the way through to a recommended remediation.
- Talk to your NetApp account team about a fleet workshop or a proof of concept.
The fastest way to judge any observability tool is to give it a problem you already have and see how far it gets you. With Console local, that is a two-week exercise—not a two-quarter one.